Every premium AI,
one subscription
Ask once. Compare ChatGPT, Claude, Gemini, Grok and DeepSeek side by side, then keep the answer that got it right.
 ChatGPTClaudeGeminiGrokDeepSeek
Pick the mode that fits the question
Prism reads the question and routes it to the model best suited to it. One answer, no decision to make.
ClaudeChosen for tone1,102 tok · 2.4sNo single model wins everything
ChatGPTClaudeGeminiGrokDeepSeekMistralLlamaDeepSeekMore than a chat window
Ask once, judge every answer
One prompt fans out to every model you enable. Replies stream in side by side, so you compare rather than guess which one to trust.
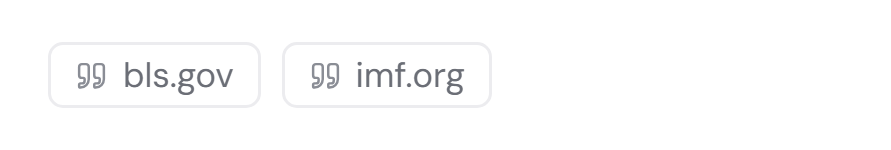
Answers that show their sources
Search runs before the model answers, and every claim carries the page it came from — so you can check the work instead of taking it on faith.
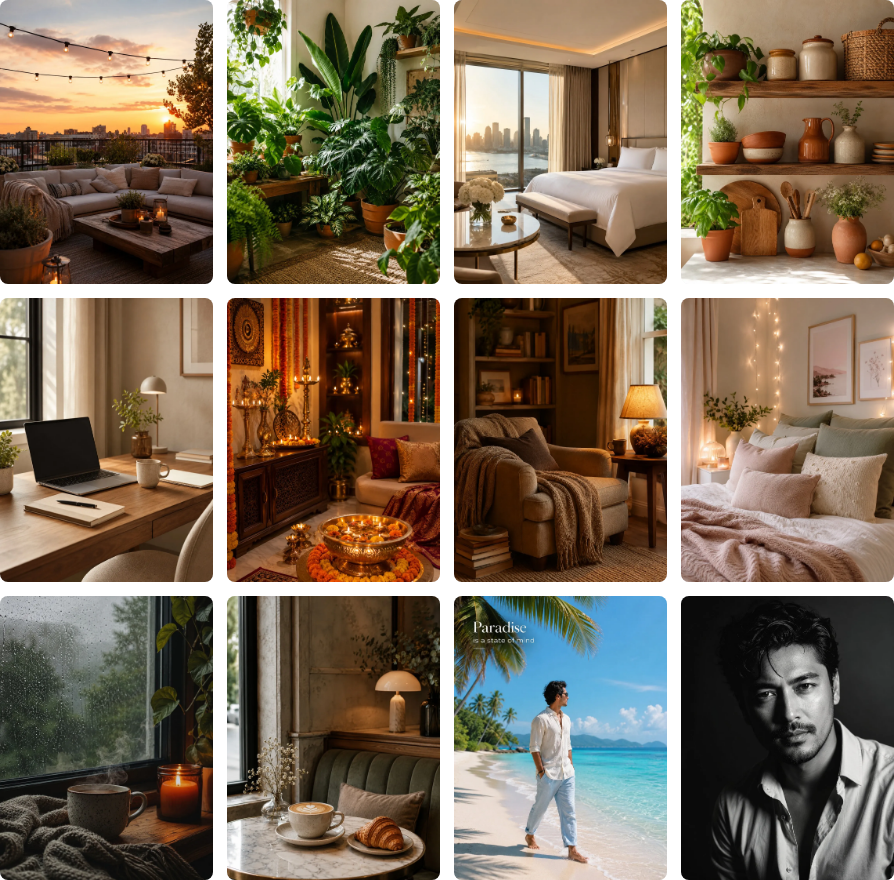
Generate images without a second subscription
Describe what you want, pick a model, aspect and count. Anything made in a chat lands in the same gallery as ImageLab work.
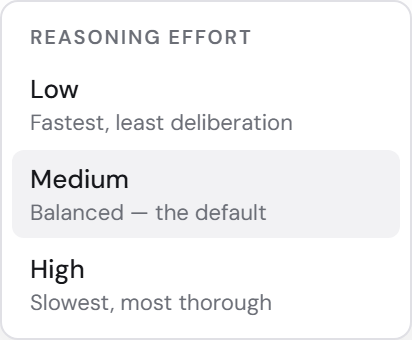
Trade speed for depth, per model
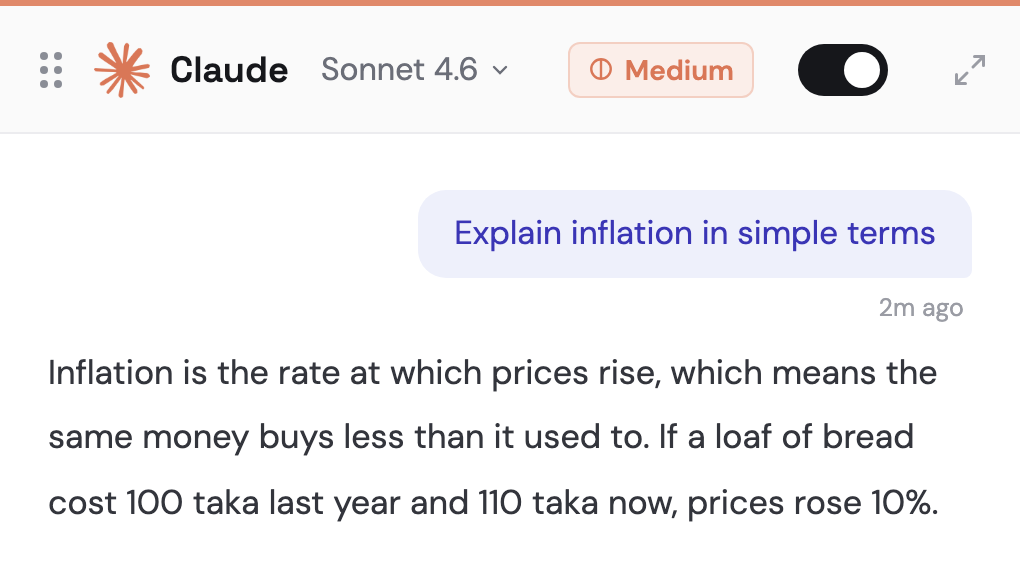
Models that support it expose a reasoning dial. Run one deep on the hard part of a question and the rest shallow on the easy part.
Context that carries between chats
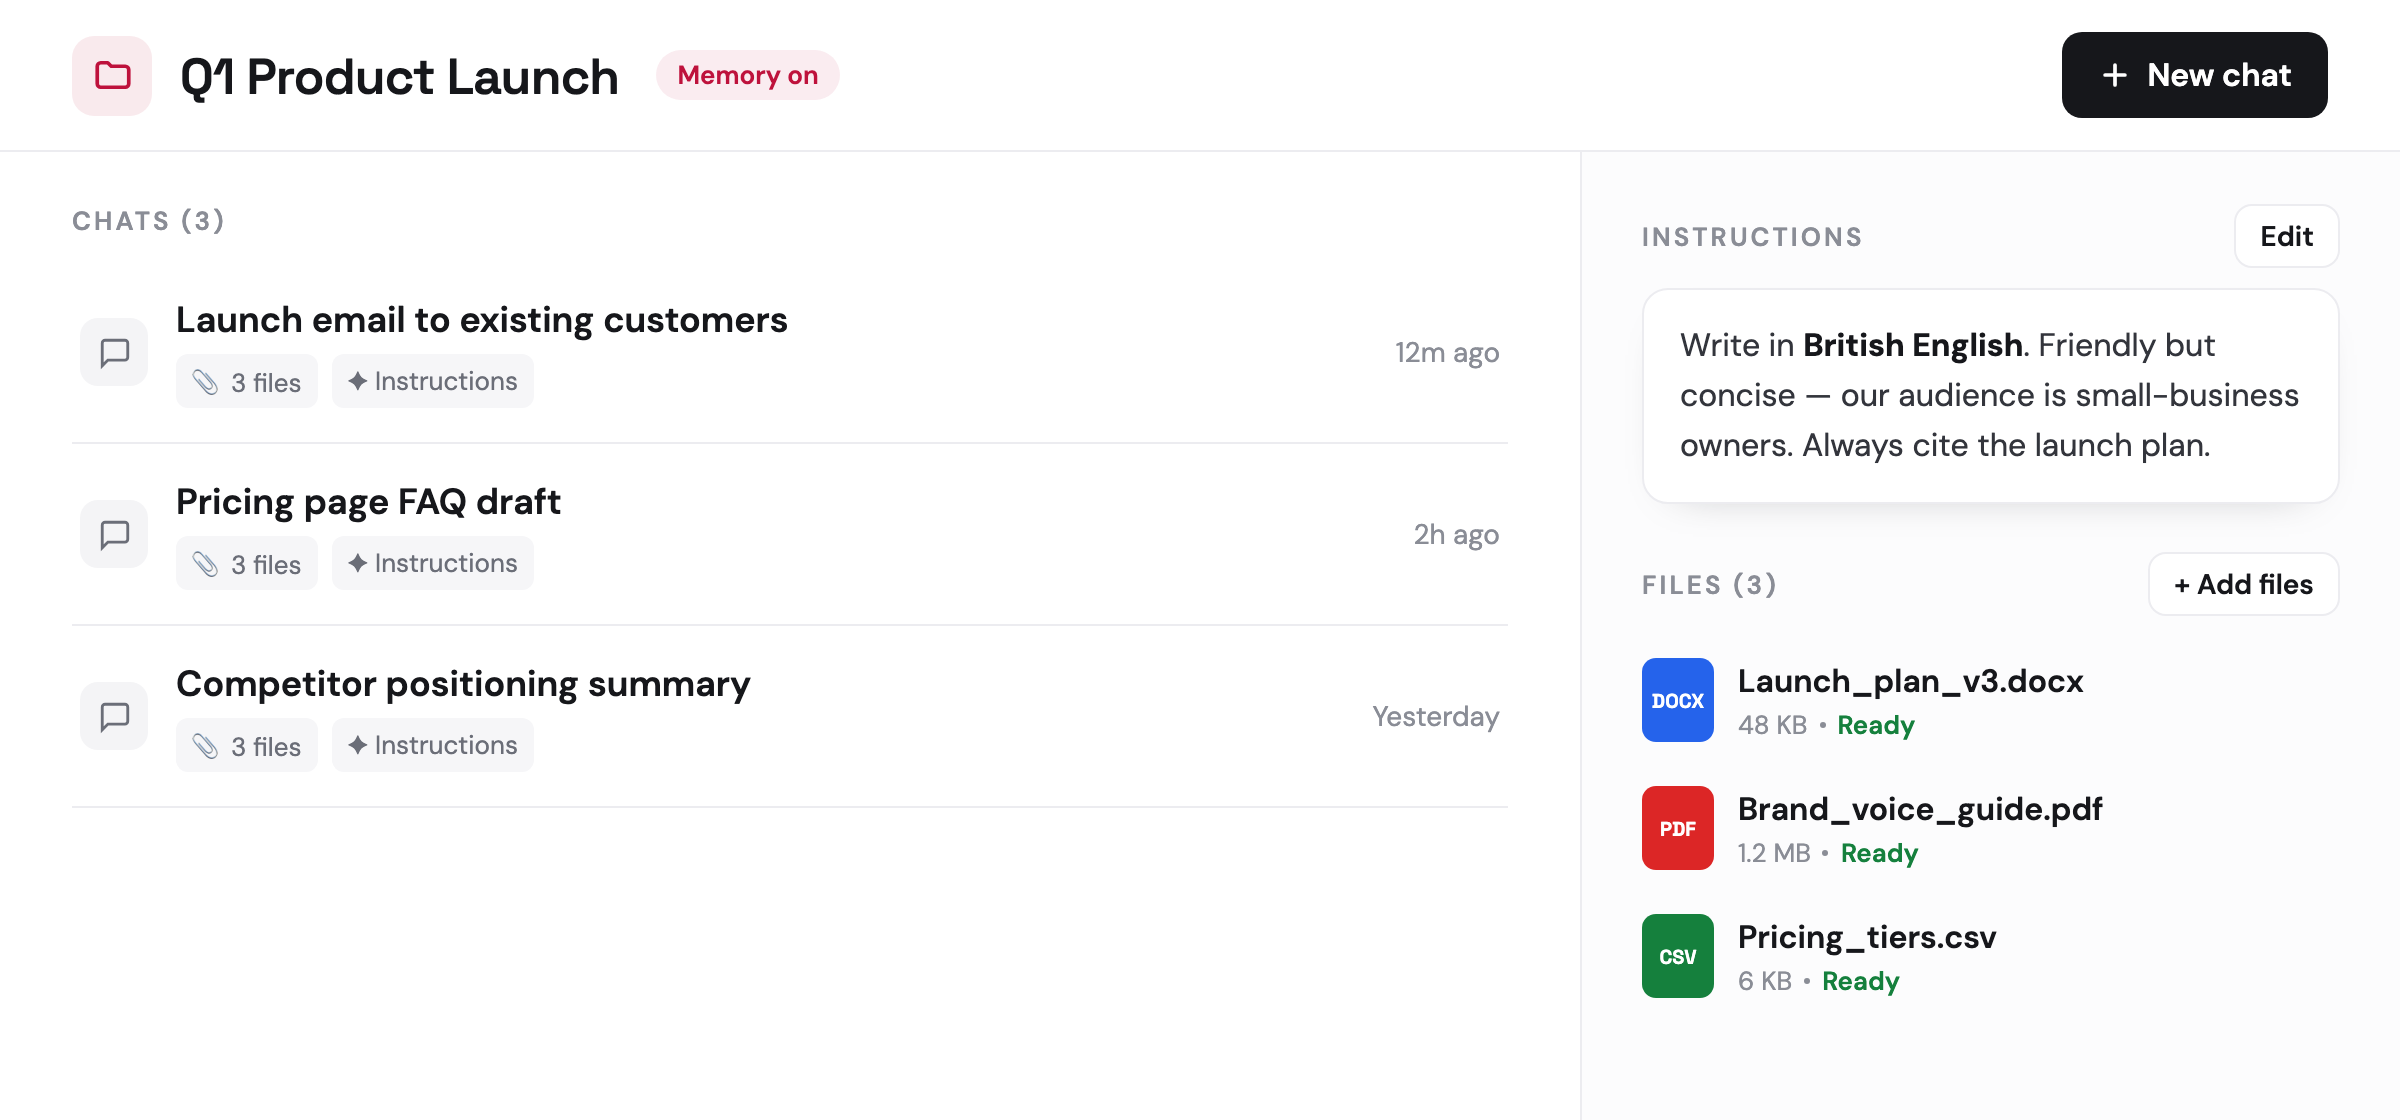
Projects hold the files and standing instructions a body of work needs, and every chat started inside one inherits them.
Three steps, no setup
One plan replaces the stack
ChatGPT Plus$20/moClaude Pro$20/moGemini Advanced$20/moGrok Premium$30/moImage generation$20/moWhat people are saying
I stopped guessing which model to open. I ask all of them and take the one that actually answered the question.
Watching them disagree is the point. When three agree and one does not, that is when I go and check the source.
One invoice instead of five, and my team stopped expensing subscriptions I had no visibility on.
Paying in taka without an international card was the thing that finally made this usable for our whole studio.
I send the same brief to four models and the consensus is usually better than any single answer was.
The reasoning-effort control is underrated. One model thinking hard, three answering fast, in the same thread.
One model is not enough
We labelled 2,400 answers from five frontier models against the same prompts. No single model was reliably right, and which one failed changed with the question.